Laravel 13 Caching: Redis, Cache Drivers & Real-World Examples
A fast Laravel application is not only about writing efficient database queries. As an application grows, repeatedly executing the same expensive queries, API requests, calculations, and configuration lookups can become a major performance bottleneck.
This is where caching becomes extremely useful.
Laravel 13 provides a powerful caching system that allows developers to store frequently used data and retrieve it quickly without repeating expensive operations. You can use simple file or database caching for smaller applications, or Redis for high-performance production workloads.
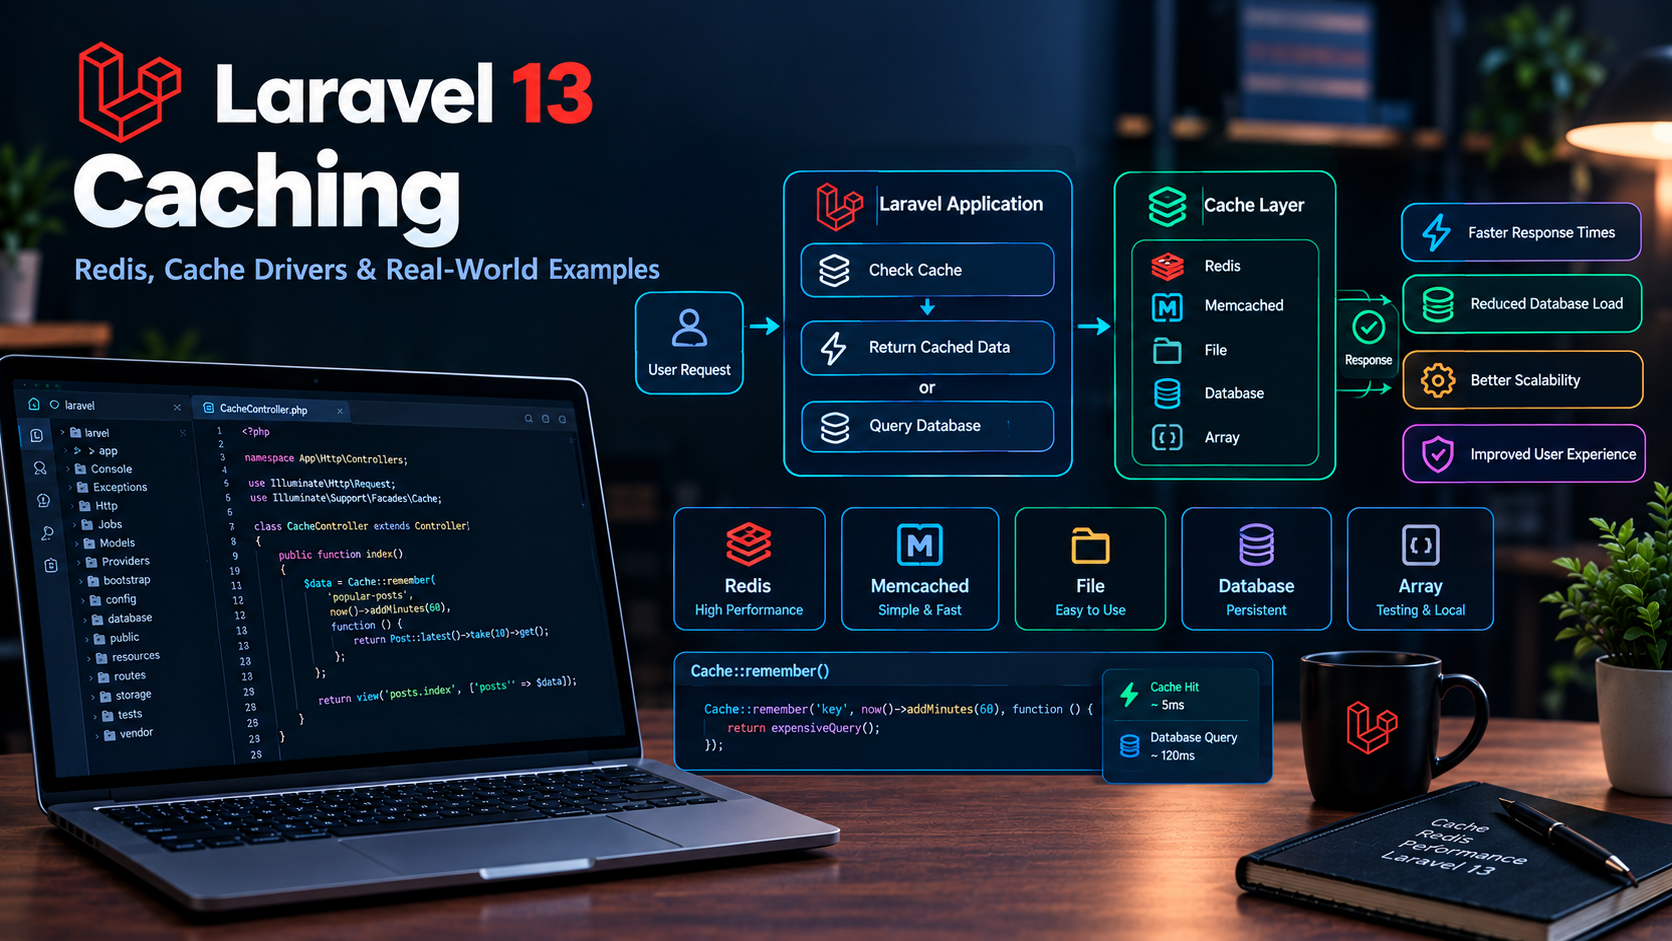
In this guide, you'll learn how Laravel 13 caching works, how to use Cache::remember(), how Redis fits into Laravel, how to choose a cache driver, and how to design a practical caching strategy for production applications.
What Is Caching?
Caching means temporarily storing data that is expensive or slow to generate so that it can be reused later.
Consider a dashboard that executes several database queries every time a user opens it.
Without caching:
User Request
     ↓
Laravel Application
     ↓
Database Queries
     ↓
Process Data
     ↓
Return Response
If thousands of users request the same information, the application may repeatedly execute the same queries.
With caching:
User Request
     ↓
Laravel Application
     ↓
Check Cache
   ↙       ↘
Hit         Miss
 ↓           ↓
Return     Database
Data       Query
              ↓
           Store Cache
              ↓
          Return Data
The second request can often avoid the expensive database operation completely.
Caching can therefore help reduce:
- Database load
- API requests
- CPU usage
- Response time
- Server resource consumption
Laravel 13 Cache Drivers
Laravel provides a consistent cache API while allowing you to choose different storage backends.
Depending on your application and environment, you can use cache stores such as:
- Database
- File
- Redis
- Memcached
- Array
- Null
- Other supported stores
The important advantage is that your application code can use Laravel's Cache API without being tightly coupled to one storage system.
For example:
use Illuminate\Support\Facades\Cache;

$value = Cache::get('homepage.data');
Your application can later move from one cache backend to another with relatively little application-code change.
Configuring the Cache Store
Laravel's cache configuration is controlled through your application's configuration and environment variables.
For example:
CACHE_STORE=database
For a Redis-based production environment:
CACHE_STORE=redis
The exact environment configuration can vary depending on how Redis is installed and configured on your server.
After changing configuration values in production, remember to clear and rebuild your Laravel configuration cache when appropriate:
php artisan config:clear
php artisan config:cache
Basic Laravel Cache Usage
The Cache facade provides simple methods for storing and retrieving values.
Store a Value
use Illuminate\Support\Facades\Cache;

Cache::put('site.name', 'Abhilash Raj', 3600);
The third argument represents the cache lifetime in seconds.
In this example, the value is cached for one hour.
Retrieve a Value
$name = Cache::get('site.name');
You can also provide a default value:
$name = Cache::get('site.name', 'Guest');
Check Whether a Key Exists
if (Cache::has('site.name')) {
    // Cache exists
}
Remove Cached Data
Cache::forget('site.name');
The Most Useful Method: Cache::remember()
One of the most useful Laravel caching patterns is:
Cache::remember()
Instead of manually checking whether data exists, Laravel can retrieve the cached value or execute a callback when the value is missing.
For example:
$posts = Cache::remember(
    'popular-posts',
    3600,
    function () {
        return Post::where('views', '>', 1000)
            ->latest()
            ->take(10)
            ->get();
    }
);
The process works like this:
Cache exists?
      │
 ┌────┴────┐
 Yes       No
 │          │
Return    Execute Query
Data        │
            ↓
        Store Result
            │
            ↓
        Return Data
This is much cleaner than manually writing cache lookup logic.
Laravel's cache repository exposes remember() specifically for retrieving an item or executing a callback and storing its result when the item is not already cached.
Real-World Example: Caching a Dashboard
Imagine your admin dashboard displays:
- Total users
- Total orders
- Revenue
- Recent transactions
- Popular products
Some of these values don't need to be calculated on every request.
Instead of:
$totalUsers = User::count();

$totalOrders = Order::count();

$totalRevenue = Order::sum('total');
you could cache them:
$totalUsers = Cache::remember(
    'dashboard.total_users',
    300,
    fn () => User::count()
);

$totalOrders = Cache::remember(
    'dashboard.total_orders',
    300,
    fn () => Order::count()
);

$totalRevenue = Cache::remember(
    'dashboard.total_revenue',
    300,
    fn () => Order::sum('total')
);
Now those expensive calculations are reused for five minutes.
Choosing the Right Cache Duration
There is no universal TTL that works for every piece of data.
A good rule is:
| Data | Example TTL |
|---|---|
| Frequently changing data | 30–60 seconds |
| Dashboard statistics | 5 minutes |
| Product catalog | 10–30 minutes |
| Categories | 1 hour |
| Configuration-like data | Several hours |
| Rarely changing content | 1 day |
| Static reference data | Longer |
The correct TTL depends on how frequently your underlying data changes and how stale the application can safely allow the result to become.
Cache Keys Matter
A good cache key should be:
- Unique
- Predictable
- Descriptive
- Easy to invalidate
Avoid:
Cache::remember('data', 3600, ...);
Prefer:
Cache::remember('products.popular', 3600, ...);
For user-specific data:
Cache::remember(
    'user.' . $user->id . '.dashboard',
    600,
    fn () => $this->buildDashboard($user)
);
For parameterized queries:
$key = "products.category.{$categoryId}.page.{$page}";

$products = Cache::remember(
    $key,
    600,
    fn () => Product::where('category_id', $categoryId)
        ->paginate(20)
);
This prevents different users or requests from accidentally sharing the wrong cached result.
Redis and Laravel 13
For many production Laravel applications, Redis is an excellent cache backend.
Redis is an in-memory data store designed for very fast data operations.
Laravel's Redis documentation recommends PhpRedis and also supports Predis when the PHP extension isn't available.
A typical environment might contain:
REDIS_CLIENT=phpredis

REDIS_HOST=127.0.0.1
REDIS_PASSWORD=null
REDIS_PORT=6379
Then your cache store can use Redis:
CACHE_STORE=redis
The exact values will depend on your Redis installation and hosting environment.
PhpRedis vs Predis
Laravel supports two common Redis clients.
PhpRedis
PhpRedis is a PHP extension.
It is generally a good choice when you control your server and can install PHP extensions.
Laravel's Redis documentation recommends using PhpRedis and notes that it may provide better performance for applications making heavy use of Redis.
Predis
Predis is a PHP package that doesn't require the PhpRedis extension.
Install it with:
composer require predis/predis
This can be useful when you don't have permission or ability to install PHP extensions.
Caching Eloquent Queries
Caching database results is one of the easiest ways to improve application performance.
For example:
$categories = Cache::remember(
    'categories.all',
    3600,
    fn () => Category::orderBy('name')->get()
);
Instead of running:
SELECT * FROM categories ORDER BY name;
on every request, Laravel can retrieve the result from the cache.
This is especially useful for data such as:
- Categories
- Countries
- States
- Navigation menus
- Popular posts
- Product lists
- Settings
- Frequently requested reports
Cache Expensive API Requests
Caching isn't limited to database queries.
Suppose your application calls an external API:
$response = Http::get('https://example.com/api/products');
Repeated API requests can increase:
- API costs
- Network traffic
- Response time
- Dependency on third-party services
You can cache the result:
$products = Cache::remember(
    'external.products',
    900,
    function () {
        return Http::get(
            'https://example.com/api/products'
        )->json();
    }
);
Now the external API is called only when the cached value expires or is removed.
Cache Invalidation
One of the most important caching concepts is cache invalidation.
Imagine you cache a product:
$product = Cache::remember(
    "product.{$id}",
    3600,
    fn () => Product::findOrFail($id)
);
Then an administrator updates the product.
The database contains the new information, but the cache may still contain the old version.
You can explicitly remove it:
Cache::forget("product.{$id}");
Then the next request retrieves the updated product from the database and stores it again.
Cache Invalidation After Model Updates
A common approach is to clear related cache entries after updating a model.
For example:
$product->update($data);

Cache::forget("product.{$product->id}");
For more complex applications, you can centralize this logic using model observers, events, services, or dedicated cache-management classes.
The important principle is:
Whenever important data changes, decide which cached representations are no longer valid.
Avoid Caching Everything
Caching is powerful, but caching every query is usually a mistake.
Don't automatically cache:
- Highly dynamic data
- Frequently changing records
- User-specific sensitive data without careful key design
- Data where stale information could cause financial or business problems
- Very cheap queries where caching adds more complexity than value
For example, caching a simple query that takes 1 ms may not provide meaningful benefits.
Instead, focus on operations that are:
- Expensive
- Repeated frequently
- Stable for a period of time
- Expensive to calculate
- Dependent on external services
Cache Tags
Some cache stores support cache tags, which can help organize related cached items.
For example:
Cache::tags(['products'])->put(
    'popular',
    $products,
    3600
);
You can then flush the related cache entries:
Cache::tags(['products'])->flush();
This can be useful when a particular group of cached data needs to be invalidated together.
Before relying on tags, verify that the selected cache driver supports the features you need.
Laravel Cache Atomic Locks
Caching can also be used for distributed locking.
Suppose two workers attempt to process the same operation at the same time.
You can use an atomic lock:
$lock = Cache::lock('process-report', 120);

if ($lock->get()) {
    try {
        // Perform the operation
    } finally {
        $lock->release();
    }
}
This can help prevent duplicate work in distributed applications.
Laravel's cache system provides atomic lock support, and the lock is especially useful when multiple processes or servers need to coordinate access to a shared operation.
Preventing Duplicate Expensive Calculations
Consider a report that takes 30 seconds to generate.
If 50 users request the same report simultaneously, you don't want 50 processes generating the same result.
A lock can help coordinate the work.
Conceptually:
50 Requests
     ↓
Acquire Lock
     ↓
One request generates report
     ↓
Cache result
     ↓
Other requests use cached result
This pattern can dramatically reduce unnecessary server work.
Laravel 13 Flexible Caching
Laravel 13 also exposes the flexible() cache API, which supports a stale-while-revalidate style approach.
The basic idea is:
$value = Cache::flexible(
    'popular.products',
    [60, 300],
    function () {
        return Product::popular()->get();
    }
);
This approach can allow applications to serve a recently cached value while refreshing stale data in the background, depending on the configured behavior.
Laravel's current cache API documents flexible() alongside remember(), rememberForever(), and touch().
This can be particularly useful for high-traffic pages where you want to avoid making users wait for a full cache regeneration.
Cache::touch()
Laravel 13 also provides:
Cache::touch(...)
This allows an existing cache item's TTL to be extended without retrieving and storing the complete value again.
For applications with more advanced cache lifecycle requirements, this can simplify TTL management.
Caching Configuration
Laravel configuration is commonly cached during deployment:
php artisan config:cache
This creates a cached configuration representation that Laravel can load efficiently.
When changing environment variables in production, make sure the application configuration cache is refreshed.
A typical deployment sequence might include:
php artisan optimize:clear
php artisan config:cache
php artisan route:cache
php artisan view:cache
Only use the commands appropriate for your deployment process.
Redis for High-Traffic Applications
As your application grows, Redis becomes increasingly useful because it can serve more than just application cache.
A Laravel application may use Redis for:
- Cache
- Queues
- Rate limiting
- Locks
- Sessions
- Temporary data
- Counters
- Pub/Sub
- Application-specific data structures
Laravel's Redis integration supports multiple Redis connections, clustering, transactions, and pipelining.
This makes Redis a useful building block for scalable Laravel applications.
Example: High-Traffic Blog
Imagine your Laravel blog has 100,000 visitors per day.
Your homepage displays:
- Latest articles
- Popular articles
- Categories
- Trending posts
Without caching, every request could trigger multiple database queries.
A better approach is:
$latest = Cache::remember(
    'blog.latest',
    300,
    fn () => Post::published()
        ->latest('published_at')
        ->take(10)
        ->get()
);

$popular = Cache::remember(
    'blog.popular',
    600,
    fn () => Post::published()
        ->orderByDesc('views')
        ->take(10)
        ->get()
);
The database doesn't need to calculate the same result for every visitor.
Example: Caching API Data
For an API endpoint:
public function index()
{
    $users = Cache::remember(
        'api.users',
        300,
        fn () => User::select(
            'id',
            'name',
            'email'
        )->latest()->get()
    );

    return response()->json($users);
}
This can significantly reduce database activity when the endpoint receives repeated requests.
Example: User-Specific Cache
Be careful when caching data that belongs to individual users.
Bad:
Cache::remember('dashboard', 600, function () {
    return auth()->user()->orders;
});
This could cause users to receive the wrong cached data because every user shares the same key.
Instead:
$userId = auth()->id();

$orders = Cache::remember(
    "user.{$userId}.orders",
    600,
    fn () => auth()->user()->orders
);
The cache key now contains the user identifier.
This is an important security and correctness consideration.
Cache Key Versioning
Sometimes you change the structure of cached data.
Instead of:
'products.popular'
you can use:
'v2.products.popular'
This provides a simple way to invalidate an old cache namespace without manually deleting every old key.
For larger systems, versioned keys can make deployments safer.
Don't Cache Sensitive Information Carelessly
Caching private information requires careful consideration.
Be especially careful with:
- Authentication data
- Payment information
- Personal information
- Private API responses
- Authorization results
- User-specific dashboards
If sensitive information must be cached, use appropriately scoped cache keys, secure infrastructure, suitable TTLs, and access controls.
Redis Production Checklist
If you're deploying Laravel with Redis in production, check the following:
- Redis is protected from public internet access
- Authentication is configured where appropriate
- Firewall rules are restrictive
- Redis uses appropriate memory limits
- Eviction behavior is understood
- Applications use meaningful key prefixes
- Cache TTLs are defined
- Sensitive information is handled carefully
- Redis monitoring is configured
- Backups are considered where Redis stores persistent application data
- Application and Redis servers have appropriate network connectivity
Laravel's Redis configuration supports connection details such as host, port, username, password, database, and connection options.
Common Laravel Caching Mistakes
1. Using extremely long TTLs
A cache that never expires can eventually become stale.
Prefer a deliberate TTL unless permanent caching is genuinely required.
2. Forgetting cache invalidation
Updating the database doesn't automatically mean every related cache entry becomes invalid.
Plan invalidation when designing the feature.
3. Using generic cache keys
Avoid:
'data'
Prefer:
'products.featured'
4. Sharing user-specific cache
Always include the appropriate user or tenant identifier.
5. Caching everything
Caching adds complexity.
Cache data where the performance benefit justifies the additional lifecycle management.
6. Using Redis without monitoring
Redis is fast, but production systems still need monitoring and capacity planning.
A Practical Laravel Caching Strategy
For a typical Laravel production application, I recommend starting with this approach:
Step 1 — Identify expensive operations
Find:
- Slow database queries
- Repeated API requests
- Expensive calculations
- Large datasets
- Frequently requested pages
Step 2 — Measure first
Use application monitoring and database profiling to identify actual bottlenecks.
Step 3 — Add targeted caching
Start with:
Cache::remember()
rather than introducing complicated caching architecture immediately.
Step 4 — Choose an appropriate TTL
Ask:
How stale can this data safely be?
Then choose the TTL accordingly.
Step 5 — Design invalidation
Determine what happens when the underlying data changes.
Step 6 — Move to Redis when appropriate
Redis is an excellent choice when your application needs fast centralized caching across multiple workers or servers.
Useful Laravel Cache Commands
You can inspect available Artisan commands with:
php artisan list
For clearing application caches during deployment or troubleshooting:
php artisan optimize:clear
Then rebuild the caches required by your production deployment:
php artisan config:cache
php artisan route:cache
php artisan view:cache
Always test your deployment workflow in your own environment before applying it automatically to production.
Laravel 13 Caching Best Practices
Here is a practical checklist:
- Use
Cache::remember()for repeated expensive operations. - Use meaningful cache keys.
- Choose TTLs based on how frequently data changes.
- Invalidate cache when important underlying data changes.
- Use Redis for high-performance centralized caching.
- Keep user-specific data isolated by cache key.
- Don't cache everything.
- Monitor Redis memory and performance.
- Protect Redis from public access.
- Use atomic locks when multiple workers can perform the same operation.
- Consider stale-while-revalidate patterns for high-traffic content.
- Test cache behavior after deployments.
- Measure performance before and after introducing caching.
Conclusion
Caching is one of the most effective ways to improve a Laravel application's performance when it is applied strategically.
Laravel 13 provides a clean caching API that lets you start with simple methods such as:
Cache::remember()
and scale toward more advanced solutions using Redis, atomic locks, flexible caching, and distributed application architectures.
The key isn't to cache everything.
The goal is to identify expensive operations that happen repeatedly, cache the right data for the right amount of time, and build a reliable invalidation strategy.
For most production Laravel applications, a combination of efficient database queries + targeted caching + Redis + proper cache invalidation can provide a strong foundation for performance and scalability.
Continue Learning
If you're optimizing a Laravel 13 application, these related guides are useful next steps:
- Laravel 13 Performance Optimization: Practical Tips to Make Your Application Faster
- Laravel 13 Database Optimization: Eloquent, Indexing & Query Performance
- Laravel 13 Queues & Jobs: A Practical Guide to Background Processing
- How to Deploy a Laravel Application on a VPS | Step-by-Step Guide
Together, these techniques cover some of the most important areas of Laravel application performance: database optimization, caching, background jobs, and production deployment.